A local-first tool that scores a resume against any number of job descriptions, tells me exactly where the gaps are, and packages everything I need to tailor each application. I built it to get my resume past Applicant Tracking Systems and stay highly visible to recruiters during an active job search across both government contracting and commercial roles.
Overview
Most companies run resumes through an ATS before a human ever sees them. A strong background does not matter if the software files you below the fold. I needed to own that feedback loop myself: paste in a job description, get an honest match score in minutes, see which skills are matched, mismatched, or missing, and produce a tailored resume that clears the gate.
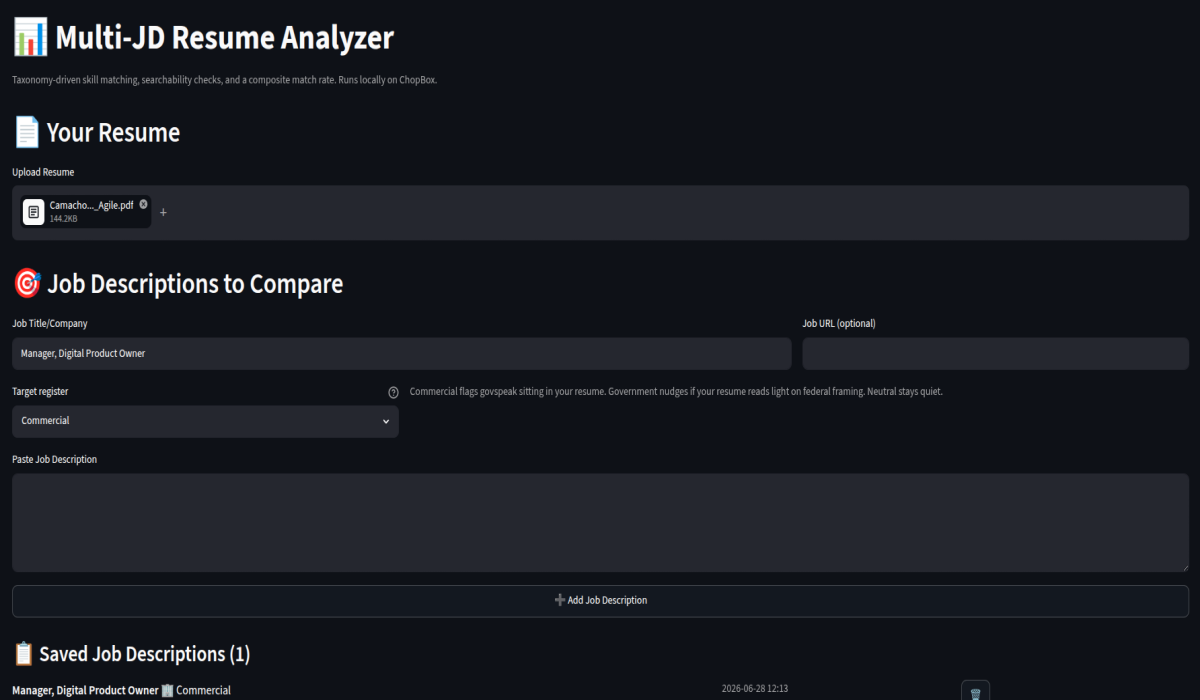 ATS Resume Matcher
This tool does that. It runs entirely on my own hardware, uses a curated skills vocabulary tuned to my target roles, and is built to handle the reality that I apply to both federal and commercial positions, which speak different dialects.
Tech Stack
- Python 3 with Streamlit for the interface and dashboarding
- spaCy (
en_core_web_trf) for tokenization, noun-chunking, and entity filtering - sentence-transformers (
all-MiniLM-L6-v2) for semantic similarity and concept-anchored relevance scoring - pdfplumber and docx2txt for resume text extraction
- plotly for the match-rate gauge and category breakdowns
- PyYAML for the editable skills taxonomy
- Designed to run locally, with optional future containerization
Architecture
%3btext-align:center%3b%7d%23mermaid-0 .edgeLabel p%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .edgeLabel rect%7bopacity:0.5%3bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bfill:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .labelBkg%7bbackground-color:rgba(232%2c 232%2c 232%2c 0.5)%3b%7d%23mermaid-0 .cluster rect%7bfill:%23ffffde%3bstroke:%23aaaa33%3bstroke-width:1px%3b%7d%23mermaid-0 .cluster text%7bfill:%23333%3b%7d%23mermaid-0 .cluster span%7bcolor:%23333%3b%7d%23mermaid-0 .node .collapsed-indicator%7bfill:%23aaaa33%3bstroke:none%3bopacity:0.6%3b%7d%23mermaid-0 .node .collapsed-separator%7bstroke:%23aaaa33%3bstroke-width:0.75px%3b%7d%23mermaid-0 div.mermaidTooltip%7bposition:absolute%3btext-align:center%3bmax-width:200px%3bpadding:2px%3bfont-family:arial%2csans-serif%3bfont-size:12px%3bbackground:hsl(80%2c 100%25%2c 96.2745098039%25)%3bborder:1px solid %23aaaa33%3bborder-radius:2px%3bpointer-events:none%3bz-index:100%3b%7d%23mermaid-0 .flowchartTitleText%7btext-anchor:middle%3bfont-size:18px%3bfill:%23333%3b%7d%23mermaid-0 rect.text%7bfill:none%3bstroke-width:0%3b%7d%23mermaid-0 .icon-shape%2c%23mermaid-0 .image-shape%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3btext-align:center%3b%7d%23mermaid-0 .icon-shape p%2c%23mermaid-0 .image-shape p%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bpadding:2px%3b%7d%23mermaid-0 .icon-shape .label rect%2c%23mermaid-0 .image-shape .label rect%7bopacity:0.5%3bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bfill:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .label-icon%7bdisplay:inline-block%3bheight:1em%3boverflow:visible%3bvertical-align:-0.125em%3b%7d%23mermaid-0 .node .label-icon path%7bfill:currentColor%3bstroke:revert%3bstroke-width:revert%3b%7d%23mermaid-0 .node .neo-node%7bstroke:%239370DB%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node rect%2c%23mermaid-0 %5bdata-look='neo'%5d.cluster rect%2c%23mermaid-0 %5bdata-look='neo'%5d.node polygon%7bstroke:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.swimlane.cluster rect%7bfilter:none%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node path%7bstroke:%239370DB%3bstroke-width:1px%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node .outer-path%7bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node .neo-line path%7bstroke:%239370DB%3bfilter:none%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node circle%7bstroke:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.node circle .state-start%7bfill:black%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.icon-shape .icon%7bfill:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 %5bdata-look='neo'%5d.icon-shape .icon-neo path%7bstroke:%239370DB%3bfilter:drop-shadow(1px 2px 2px rgba(185%2c 185%2c 185%2c 1))%3b%7d%23mermaid-0 :root%7b--mermaid-font-family:arial%2csans-serif%3b%7d%3c/style%3e%3cg%3e%3cmarker id='mermaid-0_flowchart-v2-pointEnd' class='marker flowchart-v2' viewBox='0 0 10 10' refX='5' refY='5' markerUnits='userSpaceOnUse' markerWidth='8' markerHeight='8' orient='auto'%3e%3cpath d='M 0 0 L 10 5 L 0 10 z' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-pointStart' class='marker flowchart-v2' viewBox='0 0 10 10' refX='4.5' refY='5' markerUnits='userSpaceOnUse' markerWidth='8' markerHeight='8' orient='auto'%3e%3cpath d='M 0 5 L 10 10 L 10 0 z' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-pointEnd-margin' class='marker flowchart-v2' viewBox='0 0 11.5 14' refX='11.5' refY='7' markerUnits='userSpaceOnUse' markerWidth='10.5' markerHeight='14' orient='auto'%3e%3cpath d='M 0 0 L 11.5 7 L 0 14 z' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-pointStart-margin' class='marker flowchart-v2' viewBox='0 0 11.5 14' refX='1' refY='7' markerUnits='userSpaceOnUse' markerWidth='11.5' markerHeight='14' orient='auto'%3e%3cpolygon points='0%2c7 11.5%2c14 11.5%2c0' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleEnd' class='marker flowchart-v2' viewBox='0 0 10 10' refX='11' refY='5' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleStart' class='marker flowchart-v2' viewBox='0 0 10 10' refX='-1' refY='5' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleEnd-margin' class='marker flowchart-v2' viewBox='0 0 10 10' refY='5' refX='12.25' markerUnits='userSpaceOnUse' markerWidth='14' markerHeight='14' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-circleStart-margin' class='marker flowchart-v2' viewBox='0 0 10 10' refX='-2' refY='5' markerUnits='userSpaceOnUse' markerWidth='14' markerHeight='14' orient='auto'%3e%3ccircle cx='5' cy='5' r='5' class='arrowMarkerPath' style='stroke-width: 0%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossEnd' class='marker cross flowchart-v2' viewBox='0 0 11 11' refX='12' refY='5.2' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3cpath d='M 1%2c1 l 9%2c9 M 10%2c1 l -9%2c9' class='arrowMarkerPath' style='stroke-width: 2%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossStart' class='marker cross flowchart-v2' viewBox='0 0 11 11' refX='-1' refY='5.2' markerUnits='userSpaceOnUse' markerWidth='11' markerHeight='11' orient='auto'%3e%3cpath d='M 1%2c1 l 9%2c9 M 10%2c1 l -9%2c9' class='arrowMarkerPath' style='stroke-width: 2%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossEnd-margin' class='marker cross flowchart-v2' viewBox='0 0 15 15' refX='17.7' refY='7.5' markerUnits='userSpaceOnUse' markerWidth='12' markerHeight='12' orient='auto'%3e%3cpath d='M 1%2c1 L 14%2c14 M 1%2c14 L 14%2c1' class='arrowMarkerPath' style='stroke-width: 2.5%3b'/%3e%3c/marker%3e%3cmarker id='mermaid-0_flowchart-v2-crossStart-margin' class='marker cross flowchart-v2' viewBox='0 0 15 15' refX='-3.5' refY='7.5' markerUnits='userSpaceOnUse' markerWidth='12' markerHeight='12' orient='auto'%3e%3cpath d='M 1%2c1 L 14%2c14 M 1%2c14 L 14%2c1' class='arrowMarkerPath' style='stroke-width: 2.5%3b stroke-dasharray: 1%2c 0%3b'/%3e%3c/marker%3e%3cg class='root'%3e%3cg class='clusters'%3e%3cg class='cluster' id='mermaid-0-PERJD' data-look='classic'%3e%3crect style='' x='27.7578125' y='312' width='1319.40234375' height='1040.4264678955078'/%3e%3cg class='cluster-label' transform='translate(612.943359375%2c 312)'%3e%3cforeignObject width='149.03125' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3ePer job description%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3cg class='edgePaths'%3e%3cpath d='M1108.711%2c54.758L988.135%2c64.131C867.56%2c73.505%2c626.409%2c92.253%2c505.833%2c111.126C385.258%2c130%2c385.258%2c149%2c385.258%2c158.5L385.258%2c168' id='mermaid-0-L_R_EX_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_R_EX_0' data-points='W3sieCI6MTEwOC43MTA5Mzc1LCJ5Ijo1NC43NTc3NDEzOTk3NjI3NX0seyJ4IjozODUuMjU3ODEyNSwieSI6MTExfSx7IngiOjM4NS4yNTc4MTI1LCJ5IjoxNzJ9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1775.004%2c999.426L1775.004%2c1003.593C1775.004%2c1007.76%2c1775.004%2c1016.093%2c1775.004%2c1023.76C1775.004%2c1031.426%2c1775.004%2c1038.426%2c1775.004%2c1041.926L1775.004%2c1045.426' id='mermaid-0-L_T_MK_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_T_MK_0' data-points='W3sieCI6MTc3NS4wMDM5MDYyNSwieSI6OTk5LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTc3NS4wMDM5MDYyNSwieSI6MTAyNC40MjY0Njc4OTU1MDc4fSx7IngiOjE3NzUuMDAzOTA2MjUsInkiOjEwNDkuNDI2NDY3ODk1NTA3OH1d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M404.36%2c226L411.552%2c236.167C418.745%2c246.333%2c433.13%2c266.667%2c440.323%2c281C447.516%2c295.333%2c447.516%2c303.667%2c453.394%2c311.638C459.273%2c319.609%2c471.03%2c327.218%2c476.908%2c331.022L482.787%2c334.827' id='mermaid-0-L_EX_SC_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_EX_SC_0' data-points='W3sieCI6NDA0LjM1OTY0MTMzNTIyNzI1LCJ5IjoyMjZ9LHsieCI6NDQ3LjUxNTYyNSwieSI6Mjg3fSx7IngiOjQ0Ny41MTU2MjUsInkiOjMxMn0seyJ4Ijo0ODYuMTQ1MDk2NjI4Mjg5NSwieSI6MzM3fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1645.004%2c1082.119L1576.728%2c1072.503C1508.452%2c1062.888%2c1371.9%2c1043.657%2c1303.624%2c1018.673C1235.348%2c993.689%2c1235.348%2c962.951%2c1235.348%2c928.213C1235.348%2c893.475%2c1235.348%2c854.738%2c1235.348%2c818.702C1235.348%2c782.667%2c1235.348%2c749.333%2c1235.348%2c718C1235.348%2c686.667%2c1235.348%2c657.333%2c1235.348%2c628C1235.348%2c598.667%2c1235.348%2c569.333%2c1235.348%2c542C1235.348%2c514.667%2c1235.348%2c489.333%2c1145.944%2c466.531C1056.54%2c443.729%2c877.732%2c423.459%2c788.328%2c413.323L698.924%2c403.188' id='mermaid-0-L_MK_SC_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_MK_SC_0' data-points='W3sieCI6MTY0NS4wMDM5MDYyNSwieSI6MTA4Mi4xMTg1MTcyMzI0N30seyJ4IjoxMjM1LjM0NzY1NjI1LCJ5IjoxMDI0LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTIzNS4zNDc2NTYyNSwieSI6OTMyLjIxMzIzMzk0Nzc1Mzl9LHsieCI6MTIzNS4zNDc2NTYyNSwieSI6ODE2fSx7IngiOjEyMzUuMzQ3NjU2MjUsInkiOjcxNn0seyJ4IjoxMjM1LjM0NzY1NjI1LCJ5Ijo2Mjh9LHsieCI6MTIzNS4zNDc2NTYyNSwieSI6NTQwfSx7IngiOjEyMzUuMzQ3NjU2MjUsInkiOjQ2NH0seyJ4Ijo2OTQuOTQ5MjE4NzUsInkiOjQwMi43Mzc1MDQ1MTU3MzgwN31d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M682.243%2c262L674.778%2c266.167C667.312%2c270.333%2c652.381%2c278.667%2c644.915%2c287C637.449%2c295.333%2c637.449%2c303.667%2c633.935%2c311.518C630.42%2c319.369%2c623.391%2c326.737%2c619.876%2c330.421L616.362%2c334.106' id='mermaid-0-L_J_SC_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_J_SC_0' data-points='W3sieCI6NjgyLjI0MzQ3NDc4NjkzMTgsInkiOjI2Mn0seyJ4Ijo2MzcuNDQ5MjE4NzUsInkiOjI4N30seyJ4Ijo2MzcuNDQ5MjE4NzUsInkiOjMxMn0seyJ4Ijo2MTMuNjAwNTM0NTM5NDczNiwieSI6MzM3fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M564.949%2c439L564.949%2c443.167C564.949%2c447.333%2c564.949%2c455.667%2c564.949%2c465.333C564.949%2c475%2c564.949%2c486%2c564.949%2c491.5L564.949%2c497' id='mermaid-0-L_SC_COV_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_SC_COV_0' data-points='W3sieCI6NTY0Ljk0OTIxODc1LCJ5Ijo0Mzl9LHsieCI6NTY0Ljk0OTIxODc1LCJ5Ijo0NjR9LHsieCI6NTY0Ljk0OTIxODc1LCJ5Ijo1MDF9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M694.949%2c407.549L757.516%2c416.957C820.082%2c426.366%2c945.215%2c445.183%2c1007.781%2c458.091C1070.348%2c471%2c1070.348%2c478%2c1070.348%2c481.5L1070.348%2c485' id='mermaid-0-L_SC_DISC_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_SC_DISC_0' data-points='W3sieCI6Njk0Ljk0OTIxODc1LCJ5Ijo0MDcuNTQ4OTMyNjE4MTM4NTZ9LHsieCI6MTA3MC4zNDc2NTYyNSwieSI6NDY0fSx7IngiOjEwNzAuMzQ3NjU2MjUsInkiOjQ4OX1d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M339.948%2c226L322.887%2c236.167C305.826%2c246.333%2c271.704%2c266.667%2c254.643%2c281C237.582%2c295.333%2c237.582%2c303.667%2c237.582%2c320.5C237.582%2c337.333%2c237.582%2c362.667%2c237.582%2c388C237.582%2c413.333%2c237.582%2c438.667%2c241.097%2c455.018C244.611%2c471.369%2c251.64%2c478.737%2c255.155%2c482.421L258.67%2c486.106' id='mermaid-0-L_EX_SRCH_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_EX_SRCH_0' data-points='W3sieCI6MzM5Ljk0ODE5Nzc5ODI5NTQ0LCJ5IjoyMjZ9LHsieCI6MjM3LjU4MjAzMTI1LCJ5IjoyODd9LHsieCI6MjM3LjU4MjAzMTI1LCJ5IjozMTJ9LHsieCI6MjM3LjU4MjAzMTI1LCJ5IjozODh9LHsieCI6MjM3LjU4MjAzMTI1LCJ5Ijo0NjR9LHsieCI6MjYxLjQzMDcxNTQ2MDUyNjMsInkiOjQ4OX1d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M665.125%2c224.994L613.44%2c235.328C561.755%2c245.662%2c458.385%2c266.331%2c406.701%2c280.832C355.016%2c295.333%2c355.016%2c303.667%2c355.016%2c320.5C355.016%2c337.333%2c355.016%2c362.667%2c355.016%2c388C355.016%2c413.333%2c355.016%2c438.667%2c352.891%2c454.926C350.767%2c471.186%2c346.519%2c478.371%2c344.395%2c481.964L342.271%2c485.557' id='mermaid-0-L_J_SRCH_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_J_SRCH_0' data-points='W3sieCI6NjY1LjEyNSwieSI6MjI0Ljk5MzUzODUzODAwNTQ1fSx7IngiOjM1NS4wMTU2MjUsInkiOjI4N30seyJ4IjozNTUuMDE1NjI1LCJ5IjozMTJ9LHsieCI6MzU1LjAxNTYyNSwieSI6Mzg4fSx7IngiOjM1NS4wMTU2MjUsInkiOjQ2NH0seyJ4IjozNDAuMjM0ODM3NTgyMjM2OCwieSI6NDg5fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M306.252%2c226L276.503%2c236.167C246.754%2c246.333%2c187.256%2c266.667%2c157.507%2c281C127.758%2c295.333%2c127.758%2c303.667%2c127.758%2c320.5C127.758%2c337.333%2c127.758%2c362.667%2c127.758%2c388C127.758%2c413.333%2c127.758%2c438.667%2c127.758%2c464C127.758%2c489.333%2c127.758%2c514.667%2c127.758%2c542C127.758%2c569.333%2c127.758%2c598.667%2c127.758%2c628C127.758%2c657.333%2c127.758%2c686.667%2c127.758%2c718C127.758%2c749.333%2c127.758%2c782.667%2c127.758%2c818.702C127.758%2c854.738%2c127.758%2c893.475%2c127.758%2c928.213C127.758%2c962.951%2c127.758%2c993.689%2c127.758%2c1021.724C127.758%2c1049.76%2c127.758%2c1075.093%2c127.758%2c1100.426C127.758%2c1125.76%2c127.758%2c1151.093%2c167.931%2c1173.189C208.104%2c1195.284%2c288.451%2c1214.142%2c328.624%2c1223.571L368.797%2c1233' id='mermaid-0-L_EX_REG_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_EX_REG_0' data-points='W3sieCI6MzA2LjI1MjEzMDY4MTgxODIsInkiOjIyNn0seyJ4IjoxMjcuNzU3ODEyNSwieSI6Mjg3fSx7IngiOjEyNy43NTc4MTI1LCJ5IjozMTJ9LHsieCI6MTI3Ljc1NzgxMjUsInkiOjM4OH0seyJ4IjoxMjcuNzU3ODEyNSwieSI6NDY0fSx7IngiOjEyNy43NTc4MTI1LCJ5Ijo1NDB9LHsieCI6MTI3Ljc1NzgxMjUsInkiOjYyOH0seyJ4IjoxMjcuNzU3ODEyNSwieSI6NzE2fSx7IngiOjEyNy43NTc4MTI1LCJ5Ijo4MTZ9LHsieCI6MTI3Ljc1NzgxMjUsInkiOjkzMi4yMTMyMzM5NDc3NTM5fSx7IngiOjEyNy43NTc4MTI1LCJ5IjoxMDI0LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTI3Ljc1NzgxMjUsInkiOjExMDAuNDI2NDY3ODk1NTA3OH0seyJ4IjoxMjcuNzU3ODEyNSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjM3Mi42OTE0MDYyNSwieSI6MTIzMy45MTQzOTgwNDk4MDU5fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1645.004%2c1107.817L1443.863%2c1119.252C1242.721%2c1130.687%2c840.439%2c1153.557%2c641.959%2c1168.621C443.479%2c1183.685%2c448.802%2c1190.943%2c451.463%2c1194.572L454.125%2c1198.201' id='mermaid-0-L_MK_REG_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_MK_REG_0' data-points='W3sieCI6MTY0NS4wMDM5MDYyNSwieSI6MTEwNy44MTY5ODgzODg4NTU5fSx7IngiOjQzOC4xNTYyNSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjQ1Ni40OTAxMDEyMDczODY0LCJ5IjoxMjAxLjQyNjQ2Nzg5NTUwNzh9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M755.624%2c262L753.012%2c266.167C750.399%2c270.333%2c745.174%2c278.667%2c742.562%2c287C739.949%2c295.333%2c739.949%2c303.667%2c739.949%2c320.5C739.949%2c337.333%2c739.949%2c362.667%2c739.949%2c388C739.949%2c413.333%2c739.949%2c438.667%2c739.949%2c464C739.949%2c489.333%2c739.949%2c514.667%2c739.949%2c542C739.949%2c569.333%2c739.949%2c598.667%2c739.949%2c628C739.949%2c657.333%2c739.949%2c686.667%2c739.949%2c718C739.949%2c749.333%2c739.949%2c782.667%2c739.949%2c818.702C739.949%2c854.738%2c739.949%2c893.475%2c739.949%2c928.213C739.949%2c962.951%2c739.949%2c993.689%2c739.949%2c1021.724C739.949%2c1049.76%2c739.949%2c1075.093%2c739.949%2c1100.426C739.949%2c1125.76%2c739.949%2c1151.093%2c722.698%2c1170.158C705.447%2c1189.224%2c670.944%2c1202.021%2c653.693%2c1208.419L636.442%2c1214.818' id='mermaid-0-L_J_REG_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_J_REG_0' data-points='W3sieCI6NzU1LjYyNDE1NjYwNTExMzYsInkiOjI2Mn0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjI4N30seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjMxMn0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjM4OH0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjQ2NH0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjU0MH0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjYyOH0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjcxNn0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjgxNn0seyJ4Ijo3MzkuOTQ5MjE4NzUsInkiOjkzMi4yMTMyMzM5NDc3NTM5fSx7IngiOjczOS45NDkyMTg3NSwieSI6MTAyNC40MjY0Njc4OTU1MDc4fSx7IngiOjczOS45NDkyMTg3NSwieSI6MTEwMC40MjY0Njc4OTU1MDc4fSx7IngiOjczOS45NDkyMTg3NSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjYzMi42OTE0MDYyNSwieSI6MTIxNi4yMDg4Nzc1ODk2MDM4fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M494.773%2c221.024L549.452%2c232.02C604.132%2c243.016%2c713.49%2c265.008%2c768.169%2c280.171C822.848%2c295.333%2c822.848%2c303.667%2c829.051%2c313.548C835.255%2c323.43%2c847.663%2c334.86%2c853.866%2c340.575L860.07%2c346.29' id='mermaid-0-L_EX_SEM_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_EX_SEM_0' data-points='W3sieCI6NDk0Ljc3MzQzNzUsInkiOjIyMS4wMjM3NjI5NzcyNDU3NX0seyJ4Ijo4MjIuODQ3NjU2MjUsInkiOjI4N30seyJ4Ijo4MjIuODQ3NjU2MjUsInkiOjMxMn0seyJ4Ijo4NjMuMDEyMTI5OTM0MjEwNSwieSI6MzQ5fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M925.125%2c234.624L956.98%2c243.354C988.835%2c252.083%2c1052.544%2c269.541%2c1084.399%2c282.437C1116.254%2c295.333%2c1116.254%2c303.667%2c1099.768%2c313.774C1083.282%2c323.881%2c1050.311%2c335.763%2c1033.825%2c341.703L1017.339%2c347.644' id='mermaid-0-L_J_SEM_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_J_SEM_0' data-points='W3sieCI6OTI1LjEyNSwieSI6MjM0LjYyNDMyMzM3MDkyMDQ1fSx7IngiOjExMTYuMjUzOTA2MjUsInkiOjI4N30seyJ4IjoxMTE2LjI1MzkwNjI1LCJ5IjozMTJ9LHsieCI6MTAxMy41NzU4NjM0ODY4NDIxLCJ5IjozNDl9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M532.926%2c579L526.22%2c587.167C519.514%2c595.333%2c506.103%2c611.667%2c500.023%2c625.338C493.942%2c639.009%2c495.193%2c650.017%2c495.819%2c655.521L496.444%2c661.026' id='mermaid-0-L_COV_COMP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_COV_COMP_0' data-points='W3sieCI6NTMyLjkyNTg3MDAyODQwOTEsInkiOjU3OX0seyJ4Ijo0OTIuNjkxNDA2MjUsInkiOjYyOH0seyJ4Ijo0OTYuODk1OTUxNzA0NTQ1NDQsInkiOjY2NX1d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M427.503%2c591L441.701%2c597.167C455.899%2c603.333%2c484.295%2c615.667%2c497.868%2c627.338C511.44%2c639.009%2c510.189%2c650.017%2c509.564%2c655.521L508.938%2c661.026' id='mermaid-0-L_SRCH_COMP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_SRCH_COMP_0' data-points='W3sieCI6NDI3LjUwMzM3MzU3OTU0NTQ0LCJ5Ijo1OTF9LHsieCI6NTEyLjY5MTQwNjI1LCJ5Ijo2Mjh9LHsieCI6NTA4LjQ4Njg2MDc5NTQ1NDU2LCJ5Ijo2NjV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M632.691%2c732.486L742.452%2c746.405C852.212%2c760.324%2c1071.733%2c788.162%2c1207.598%2c816.625C1343.462%2c845.089%2c1395.67%2c874.178%2c1421.774%2c888.722L1447.879%2c903.266' id='mermaid-0-L_COMP_RANK_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_COMP_RANK_0' data-points='W3sieCI6NjMyLjY5MTQwNjI1LCJ5Ijo3MzIuNDg1NjkzOTA1MDQ4N30seyJ4IjoxMjkxLjI1MzkwNjI1LCJ5Ijo4MTZ9LHsieCI6MTQ1MS4zNzI3NTM1NjEwOTQsInkiOjkwNS4yMTMyMzM5NDc3NTM5fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M372.691%2c745.89L321.869%2c757.575C271.047%2c769.26%2c169.402%2c792.63%2c118.58%2c823.684C67.758%2c854.738%2c67.758%2c893.475%2c67.758%2c928.213C67.758%2c962.951%2c67.758%2c993.689%2c67.758%2c1021.724C67.758%2c1049.76%2c67.758%2c1075.093%2c67.758%2c1100.426C67.758%2c1125.76%2c67.758%2c1151.093%2c67.758%2c1178.426C67.758%2c1205.76%2c67.758%2c1235.093%2c67.758%2c1264.426C67.758%2c1293.76%2c67.758%2c1323.093%2c67.758%2c1341.926C67.758%2c1360.76%2c67.758%2c1369.093%2c70.668%2c1376.905C73.578%2c1384.718%2c79.398%2c1392.009%2c82.308%2c1395.655L85.218%2c1399.3' id='mermaid-0-L_COMP_REP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_COMP_REP_0' data-points='W3sieCI6MzcyLjY5MTQwNjI1LCJ5Ijo3NDUuODg5NjIwMzYyMzAzOH0seyJ4Ijo2Ny43NTc4MTI1LCJ5Ijo4MTZ9LHsieCI6NjcuNzU3ODEyNSwieSI6OTMyLjIxMzIzMzk0Nzc1Mzl9LHsieCI6NjcuNzU3ODEyNSwieSI6MTAyNC40MjY0Njc4OTU1MDc4fSx7IngiOjY3Ljc1NzgxMjUsInkiOjExMDAuNDI2NDY3ODk1NTA3OH0seyJ4Ijo2Ny43NTc4MTI1LCJ5IjoxMTc2LjQyNjQ2Nzg5NTUwNzh9LHsieCI6NjcuNzU3ODEyNSwieSI6MTI2NC40MjY0Njc4OTU1MDc4fSx7IngiOjY3Ljc1NzgxMjUsInkiOjEzNTIuNDI2NDY3ODk1NTA3OH0seyJ4Ijo2Ny43NTc4MTI1LCJ5IjoxMzc3LjQyNjQ2Nzg5NTUwNzh9LHsieCI6ODcuNzEyOTc5NDAzNDA5MSwieSI6MTQwMi40MjY0Njc4OTU1MDc4fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M434.949%2c408.704L377.084%2c417.92C319.219%2c427.136%2c203.488%2c445.568%2c145.623%2c467.451C87.758%2c489.333%2c87.758%2c514.667%2c87.758%2c542C87.758%2c569.333%2c87.758%2c598.667%2c87.758%2c628C87.758%2c657.333%2c87.758%2c686.667%2c87.758%2c718C87.758%2c749.333%2c87.758%2c782.667%2c87.758%2c818.702C87.758%2c854.738%2c87.758%2c893.475%2c87.758%2c928.213C87.758%2c962.951%2c87.758%2c993.689%2c87.758%2c1021.724C87.758%2c1049.76%2c87.758%2c1075.093%2c87.758%2c1100.426C87.758%2c1125.76%2c87.758%2c1151.093%2c87.758%2c1178.426C87.758%2c1205.76%2c87.758%2c1235.093%2c87.758%2c1264.426C87.758%2c1293.76%2c87.758%2c1323.093%2c87.758%2c1341.926C87.758%2c1360.76%2c87.758%2c1369.093%2c89.806%2c1376.848C91.855%2c1384.602%2c95.951%2c1391.777%2c98%2c1395.365L100.048%2c1398.953' id='mermaid-0-L_SC_REP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_SC_REP_0' data-points='W3sieCI6NDM0Ljk0OTIxODc1LCJ5Ijo0MDguNzA0NDgwMTUzMjQwNH0seyJ4Ijo4Ny43NTc4MTI1LCJ5Ijo0NjR9LHsieCI6ODcuNzU3ODEyNSwieSI6NTQwfSx7IngiOjg3Ljc1NzgxMjUsInkiOjYyOH0seyJ4Ijo4Ny43NTc4MTI1LCJ5Ijo3MTZ9LHsieCI6ODcuNzU3ODEyNSwieSI6ODE2fSx7IngiOjg3Ljc1NzgxMjUsInkiOjkzMi4yMTMyMzM5NDc3NTM5fSx7IngiOjg3Ljc1NzgxMjUsInkiOjEwMjQuNDI2NDY3ODk1NTA3OH0seyJ4Ijo4Ny43NTc4MTI1LCJ5IjoxMTAwLjQyNjQ2Nzg5NTUwNzh9LHsieCI6ODcuNzU3ODEyNSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjg3Ljc1NzgxMjUsInkiOjEyNjQuNDI2NDY3ODk1NTA3OH0seyJ4Ijo4Ny43NTc4MTI1LCJ5IjoxMzUyLjQyNjQ2Nzg5NTUwNzh9LHsieCI6ODcuNzU3ODEyNSwieSI6MTM3Ny40MjY0Njc4OTU1MDc4fSx7IngiOjEwMi4wMzExNjEyMjE1OTA5LCJ5IjoxNDAyLjQyNjQ2Nzg5NTUwNzh9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M192.826%2c591L178.648%2c597.167C164.47%2c603.333%2c136.114%2c615.667%2c121.936%2c636.5C107.758%2c657.333%2c107.758%2c686.667%2c107.758%2c718C107.758%2c749.333%2c107.758%2c782.667%2c107.758%2c818.702C107.758%2c854.738%2c107.758%2c893.475%2c107.758%2c928.213C107.758%2c962.951%2c107.758%2c993.689%2c107.758%2c1021.724C107.758%2c1049.76%2c107.758%2c1075.093%2c107.758%2c1100.426C107.758%2c1125.76%2c107.758%2c1151.093%2c107.758%2c1178.426C107.758%2c1205.76%2c107.758%2c1235.093%2c107.758%2c1264.426C107.758%2c1293.76%2c107.758%2c1323.093%2c107.758%2c1341.926C107.758%2c1360.76%2c107.758%2c1369.093%2c108.973%2c1376.796C110.188%2c1384.499%2c112.619%2c1391.571%2c113.834%2c1395.107L115.049%2c1398.644' id='mermaid-0-L_SRCH_REP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_SRCH_REP_0' data-points='W3sieCI6MTkyLjgyNTk0OTkyODk3NzI1LCJ5Ijo1OTF9LHsieCI6MTA3Ljc1NzgxMjUsInkiOjYyOH0seyJ4IjoxMDcuNzU3ODEyNSwieSI6NzE2fSx7IngiOjEwNy43NTc4MTI1LCJ5Ijo4MTZ9LHsieCI6MTA3Ljc1NzgxMjUsInkiOjkzMi4yMTMyMzM5NDc3NTM5fSx7IngiOjEwNy43NTc4MTI1LCJ5IjoxMDI0LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTA3Ljc1NzgxMjUsInkiOjExMDAuNDI2NDY3ODk1NTA3OH0seyJ4IjoxMDcuNzU3ODEyNSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjEwNy43NTc4MTI1LCJ5IjoxMjY0LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTA3Ljc1NzgxMjUsInkiOjEzNTIuNDI2NDY3ODk1NTA3OH0seyJ4IjoxMDcuNzU3ODEyNSwieSI6MTM3Ny40MjY0Njc4OTU1MDc4fSx7IngiOjExNi4zNDkzNDMwMzk3NzI3MiwieSI6MTQwMi40MjY0Njc4OTU1MDc4fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M502.691%2c1327.426L502.691%2c1331.593C502.691%2c1335.76%2c502.691%2c1344.093%2c502.691%2c1352.426C502.691%2c1360.76%2c502.691%2c1369.093%2c464.224%2c1382.542C425.757%2c1395.991%2c348.823%2c1414.555%2c310.356%2c1423.837L271.888%2c1433.119' id='mermaid-0-L_REG_REP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_REG_REP_0' data-points='W3sieCI6NTAyLjY5MTQwNjI1LCJ5IjoxMzI3LjQyNjQ2Nzg5NTUwNzh9LHsieCI6NTAyLjY5MTQwNjI1LCJ5IjoxMzUyLjQyNjQ2Nzg5NTUwNzh9LHsieCI6NTAyLjY5MTQwNjI1LCJ5IjoxMzc3LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MjY4LCJ5IjoxNDM0LjA1NzQ4MDg0NTI0MDd9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M963.132%2c591L950.168%2c597.167C937.204%2c603.333%2c911.276%2c615.667%2c898.312%2c636.5C885.348%2c657.333%2c885.348%2c686.667%2c885.348%2c718C885.348%2c749.333%2c885.348%2c782.667%2c885.348%2c818.702C885.348%2c854.738%2c885.348%2c893.475%2c885.348%2c928.213C885.348%2c962.951%2c885.348%2c993.689%2c885.348%2c1021.724C885.348%2c1049.76%2c885.348%2c1075.093%2c885.348%2c1100.426C885.348%2c1125.76%2c885.348%2c1151.093%2c885.348%2c1178.426C885.348%2c1205.76%2c885.348%2c1235.093%2c885.348%2c1264.426C885.348%2c1293.76%2c885.348%2c1323.093%2c885.348%2c1341.926C885.348%2c1360.76%2c885.348%2c1369.093%2c783.118%2c1385.297C680.889%2c1401.501%2c476.431%2c1425.576%2c374.202%2c1437.614L271.973%2c1449.651' id='mermaid-0-L_DISC_REP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_DISC_REP_0' data-points='W3sieCI6OTYzLjEzMTc0NzE1OTA5MDksInkiOjU5MX0seyJ4Ijo4ODUuMzQ3NjU2MjUsInkiOjYyOH0seyJ4Ijo4ODUuMzQ3NjU2MjUsInkiOjcxNn0seyJ4Ijo4ODUuMzQ3NjU2MjUsInkiOjgxNn0seyJ4Ijo4ODUuMzQ3NjU2MjUsInkiOjkzMi4yMTMyMzM5NDc3NTM5fSx7IngiOjg4NS4zNDc2NTYyNSwieSI6MTAyNC40MjY0Njc4OTU1MDc4fSx7IngiOjg4NS4zNDc2NTYyNSwieSI6MTEwMC40MjY0Njc4OTU1MDc4fSx7IngiOjg4NS4zNDc2NTYyNSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjg4NS4zNDc2NTYyNSwieSI6MTI2NC40MjY0Njc4OTU1MDc4fSx7IngiOjg4NS4zNDc2NTYyNSwieSI6MTM1Mi40MjY0Njc4OTU1MDc4fSx7IngiOjg4NS4zNDc2NTYyNSwieSI6MTM3Ny40MjY0Njc4OTU1MDc4fSx7IngiOjI2OCwieSI6MTQ1MC4xMTkwMDAzNDA5Nzl9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M905.348%2c427L905.348%2c433.167C905.348%2c439.333%2c905.348%2c451.667%2c905.348%2c470.5C905.348%2c489.333%2c905.348%2c514.667%2c905.348%2c542C905.348%2c569.333%2c905.348%2c598.667%2c905.348%2c628C905.348%2c657.333%2c905.348%2c686.667%2c905.348%2c718C905.348%2c749.333%2c905.348%2c782.667%2c905.348%2c818.702C905.348%2c854.738%2c905.348%2c893.475%2c905.348%2c928.213C905.348%2c962.951%2c905.348%2c993.689%2c905.348%2c1021.724C905.348%2c1049.76%2c905.348%2c1075.093%2c905.348%2c1100.426C905.348%2c1125.76%2c905.348%2c1151.093%2c905.348%2c1178.426C905.348%2c1205.76%2c905.348%2c1235.093%2c905.348%2c1264.426C905.348%2c1293.76%2c905.348%2c1323.093%2c905.348%2c1341.926C905.348%2c1360.76%2c905.348%2c1369.093%2c799.785%2c1385.366C694.223%2c1401.638%2c483.099%2c1425.85%2c377.536%2c1437.956L271.974%2c1450.062' id='mermaid-0-L_SEM_REP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_SEM_REP_0' data-points='W3sieCI6OTA1LjM0NzY1NjI1LCJ5Ijo0Mjd9LHsieCI6OTA1LjM0NzY1NjI1LCJ5Ijo0NjR9LHsieCI6OTA1LjM0NzY1NjI1LCJ5Ijo1NDB9LHsieCI6OTA1LjM0NzY1NjI1LCJ5Ijo2Mjh9LHsieCI6OTA1LjM0NzY1NjI1LCJ5Ijo3MTZ9LHsieCI6OTA1LjM0NzY1NjI1LCJ5Ijo4MTZ9LHsieCI6OTA1LjM0NzY1NjI1LCJ5Ijo5MzIuMjEzMjMzOTQ3NzUzOX0seyJ4Ijo5MDUuMzQ3NjU2MjUsInkiOjEwMjQuNDI2NDY3ODk1NTA3OH0seyJ4Ijo5MDUuMzQ3NjU2MjUsInkiOjExMDAuNDI2NDY3ODk1NTA3OH0seyJ4Ijo5MDUuMzQ3NjU2MjUsInkiOjExNzYuNDI2NDY3ODk1NTA3OH0seyJ4Ijo5MDUuMzQ3NjU2MjUsInkiOjEyNjQuNDI2NDY3ODk1NTA3OH0seyJ4Ijo5MDUuMzQ3NjU2MjUsInkiOjEzNTIuNDI2NDY3ODk1NTA3OH0seyJ4Ijo5MDUuMzQ3NjU2MjUsInkiOjEzNzcuNDI2NDY3ODk1NTA3OH0seyJ4IjoyNjgsInkiOjE0NTAuNTE3OTcxMTk2NzUzNX1d' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M138%2c1528.426L138%2c1532.593C138%2c1536.76%2c138%2c1545.093%2c138%2c1552.76C138%2c1560.426%2c138%2c1567.426%2c138%2c1570.926L138%2c1574.426' id='mermaid-0-L_REP_EXP_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_REP_EXP_0' data-points='W3sieCI6MTM4LCJ5IjoxNTI4LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTM4LCJ5IjoxNTUzLjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTM4LCJ5IjoxNTc4LjQyNjQ2Nzg5NTUwNzh9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1198.373%2c591L1213.853%2c597.167C1229.333%2c603.333%2c1260.294%2c615.667%2c1334.794%2c632.57C1409.294%2c649.473%2c1527.333%2c670.946%2c1586.353%2c681.682L1645.373%2c692.419' id='mermaid-0-L_DISC_ADD_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_DISC_ADD_0' data-points='W3sieCI6MTE5OC4zNzI4NjkzMTgxODE4LCJ5Ijo1OTF9LHsieCI6MTI5MS4yNTM5MDYyNSwieSI6NjI4fSx7IngiOjE2NDkuMzA4NTkzNzUsInkiOjY5My4xMzQ0OTYxMjQwMzF9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1775.004%2c743L1775.004%2c755.167C1775.004%2c767.333%2c1775.004%2c791.667%2c1775.004%2c811.333C1775.004%2c831%2c1775.004%2c846%2c1775.004%2c853.5L1775.004%2c861' id='mermaid-0-L_ADD_T_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_ADD_T_0' data-points='W3sieCI6MTc3NS4wMDM5MDYyNSwieSI6NzQzfSx7IngiOjE3NzUuMDAzOTA2MjUsInkiOjgxNn0seyJ4IjoxNzc1LjAwMzkwNjI1LCJ5Ijo4NjV9XQ==' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M138%2c1680.426L138%2c1686.593C138%2c1692.76%2c138%2c1705.093%2c265.472%2c1722.078C392.945%2c1739.063%2c647.89%2c1760.7%2c775.362%2c1771.519L902.835%2c1782.337' id='mermaid-0-L_EXP_AI_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_EXP_AI_0' data-points='W3sieCI6MTM4LCJ5IjoxNjgwLjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTM4LCJ5IjoxNzE3LjQyNjQ2Nzg5NTUwNzh9LHsieCI6OTA2LjgyMDMxMjUsInkiOjE3ODIuNjc1MzE2MzA0MjE4fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3cpath d='M1160.18%2c1782.887L1291.311%2c1771.977C1422.441%2c1761.067%2c1684.703%2c1739.247%2c1815.834%2c1713.67C1946.965%2c1688.093%2c1946.965%2c1658.76%2c1946.965%2c1631.426C1946.965%2c1604.093%2c1946.965%2c1578.76%2c1946.965%2c1551.426C1946.965%2c1524.093%2c1946.965%2c1494.76%2c1946.965%2c1465.426C1946.965%2c1436.093%2c1946.965%2c1406.76%2c1946.965%2c1387.926C1946.965%2c1369.093%2c1946.965%2c1360.76%2c1946.965%2c1341.926C1946.965%2c1323.093%2c1946.965%2c1293.76%2c1946.965%2c1264.426C1946.965%2c1235.093%2c1946.965%2c1205.76%2c1946.965%2c1178.426C1946.965%2c1151.093%2c1946.965%2c1125.76%2c1946.965%2c1100.426C1946.965%2c1075.093%2c1946.965%2c1049.76%2c1946.965%2c1021.724C1946.965%2c993.689%2c1946.965%2c962.951%2c1946.965%2c928.213C1946.965%2c893.475%2c1946.965%2c854.738%2c1946.965%2c818.702C1946.965%2c782.667%2c1946.965%2c749.333%2c1946.965%2c718C1946.965%2c686.667%2c1946.965%2c657.333%2c1946.965%2c628C1946.965%2c598.667%2c1946.965%2c569.333%2c1946.965%2c542C1946.965%2c514.667%2c1946.965%2c489.333%2c1946.965%2c464C1946.965%2c438.667%2c1946.965%2c413.333%2c1946.965%2c388C1946.965%2c362.667%2c1946.965%2c337.333%2c1946.965%2c320.5C1946.965%2c303.667%2c1946.965%2c295.333%2c1946.965%2c276.5C1946.965%2c257.667%2c1946.965%2c228.333%2c1946.965%2c199C1946.965%2c169.667%2c1946.965%2c140.333%2c1841.183%2c116.499C1735.401%2c92.665%2c1523.838%2c74.329%2c1418.056%2c65.161L1312.274%2c55.994' id='mermaid-0-L_AI_R_0' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' style='%3b' data-edge='true' data-et='edge' data-id='L_AI_R_0' data-points='W3sieCI6MTE2MC4xNzk2ODc1LCJ5IjoxNzgyLjg4Njc1NjAzMjYyM30seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5IjoxNzE3LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6MTYyOS40MjY0Njc4OTU1MDc4fSx7IngiOjE5NDYuOTY0ODQzNzUsInkiOjE1NTMuNDI2NDY3ODk1NTA3OH0seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5IjoxNDY1LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6MTM3Ny40MjY0Njc4OTU1MDc4fSx7IngiOjE5NDYuOTY0ODQzNzUsInkiOjEzNTIuNDI2NDY3ODk1NTA3OH0seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5IjoxMjY0LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6MTE3Ni40MjY0Njc4OTU1MDc4fSx7IngiOjE5NDYuOTY0ODQzNzUsInkiOjExMDAuNDI2NDY3ODk1NTA3OH0seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5IjoxMDI0LjQyNjQ2Nzg5NTUwNzh9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6OTMyLjIxMzIzMzk0Nzc1Mzl9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6ODE2fSx7IngiOjE5NDYuOTY0ODQzNzUsInkiOjcxNn0seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5Ijo2Mjh9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6NTQwfSx7IngiOjE5NDYuOTY0ODQzNzUsInkiOjQ2NH0seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5IjozODh9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6MzEyfSx7IngiOjE5NDYuOTY0ODQzNzUsInkiOjI4N30seyJ4IjoxOTQ2Ljk2NDg0Mzc1LCJ5IjoxOTl9LHsieCI6MTk0Ni45NjQ4NDM3NSwieSI6MTExfSx7IngiOjEzMDguMjg5MDYyNSwieSI6NTUuNjQ4MzQ2NzA3NDMyNTQ1fV0=' data-look='classic' marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)'/%3e%3c/g%3e%3cg class='edgeLabels'%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_R_EX_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_T_MK_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_EX_SC_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_MK_SC_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_J_SC_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_SC_COV_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_SC_DISC_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_EX_SRCH_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_J_SRCH_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_EX_REG_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_MK_REG_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_J_REG_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_EX_SEM_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_J_SEM_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_COV_COMP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_SRCH_COMP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_COMP_RANK_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_COMP_REP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_SC_REP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_SRCH_REP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_REG_REP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_DISC_REP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_SEM_REP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg class='label' data-id='L_REP_EXP_0' transform='translate(0%2c 0)'%3e%3cforeignObject width='0' height='0'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel' transform='translate(1421.09869%2c 651.62034)'%3e%3cg class='label' data-id='L_DISC_ADD_0' transform='translate(-35.90625%2c -12)'%3e%3cforeignObject width='71.8125' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3cp%3eclick Add%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel' transform='translate(1775.00390625%2c 816)'%3e%3cg class='label' data-id='L_ADD_T_0' transform='translate(-100%2c -24)'%3e%3cforeignObject width='200' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='edgeLabel'%3e%3cp%3esaved permanently%2c live next scan%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel' transform='translate(138%2c 1717.4264678955078)'%3e%3cg class='label' data-id='L_EXP_AI_0' transform='translate(-33.0703125%2c -12)'%3e%3cforeignObject width='66.140625' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3cp%3ehand off%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel' transform='translate(1946.96484375%2c 932.2132339477539)'%3e%3cg class='label' data-id='L_AI_R_0' transform='translate(-29.4609375%2c -12)'%3e%3cforeignObject width='58.921875' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' class='labelBkg' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='edgeLabel'%3e%3cp%3ere-scan%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3cg class='nodes'%3e%3cg class='node default' id='mermaid-0-flowchart-R-0' data-look='classic' transform='translate(1208.5%2c 47)'%3e%3crect class='basic label-container' style='' x='-99.7890625' y='-39' width='199.578125' height='78'/%3e%3cg class='label' style='' transform='translate(-69.7890625%2c -24)'%3e%3crect/%3e%3cforeignObject width='139.578125' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eResume%3cbr /%3ePDF / DOCX / TXT%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-J-1' data-look='classic' transform='translate(795.125%2c 199)'%3e%3crect class='basic label-container' style='' x='-130' y='-63' width='260' height='126'/%3e%3cg class='label' style='' transform='translate(-100%2c -48)'%3e%3crect/%3e%3cforeignObject width='200' height='96'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eJob descriptions%3cbr /%3eeach tagged Neutral / Commercial / Government%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-T-2' data-look='classic' transform='translate(1775.00390625%2c 932.2132339477539)'%3e%3cpath d='M0%2c15.808823529411764 a107.5%2c15.808823529411764 0%2c0%2c0 215%2c0 a107.5%2c15.808823529411764 0%2c0%2c0 -215%2c0 l0%2c102.80882352941177 a107.5%2c15.808823529411764 0%2c0%2c0 215%2c0 l0%2c-102.80882352941177' class='basic label-container outer-path' style='' transform='translate(-107.5%2c -67.21323529411765)'/%3e%3cg class='label' style='' transform='translate(-100%2c -26)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eskills_taxonomy.yaml%3cbr /%3ecurated skills%2c aliases%2c register tags%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-EX-3' data-look='classic' transform='translate(385.2578125%2c 199)'%3e%3crect class='basic label-container' style='' x='-109.515625' y='-27' width='219.03125' height='54'/%3e%3cg class='label' style='' transform='translate(-79.515625%2c -12)'%3e%3crect/%3e%3cforeignObject width='159.03125' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eExtract resume text%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-MK-4' data-look='classic' transform='translate(1775.00390625%2c 1100.4264678955078)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eBuild matcher%3cbr /%3ecompiled patterns%2c case rules%2c DoW/DoD aliases%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-SC-9' data-look='classic' transform='translate(564.94921875%2c 388)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eScore skills%3cbr /%3ematched / variation / missing %2b counts%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-COV-10' data-look='classic' transform='translate(564.94921875%2c 540)'%3e%3crect class='basic label-container' style='' x='-74.8671875' y='-39' width='149.734375' height='78'/%3e%3cg class='label' style='' transform='translate(-44.8671875%2c -24)'%3e%3crect/%3e%3cforeignObject width='89.734375' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eCoverage%3cbr /%3ehard %2b soft%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-SRCH-11' data-look='classic' transform='translate(310.08203125%2c 540)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eSearchability checks%3cbr /%3etitle%2c dates%2c sections%2c education%2c results%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-REG-12' data-look='classic' transform='translate(502.69140625%2c 1264.4264678955078)'%3e%3crect class='basic label-container' style='' x='-130' y='-63' width='260' height='126'/%3e%3cg class='label' style='' transform='translate(-100%2c -48)'%3e%3crect/%3e%3cforeignObject width='200' height='96'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eRegister check%3cbr /%3egovspeak vs commercial%2c when a target is set%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-DISC-13' data-look='classic' transform='translate(1070.34765625%2c 540)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eDiscovered terms%3cbr /%3eskill-like phrases not in taxonomy%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-SEM-14' data-look='classic' transform='translate(905.34765625%2c 388)'%3e%3crect class='basic label-container' style='' x='-110.796875' y='-39' width='221.59375' height='78'/%3e%3cg class='label' style='' transform='translate(-80.796875%2c -24)'%3e%3crect/%3e%3cforeignObject width='161.59375' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eSemantic similarity%3cbr /%3esupplemental signal%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-COMP-15' data-look='classic' transform='translate(502.69140625%2c 716)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eComposite match rate%3cbr /%3e0.55 hard %2b 0.15 soft %2b 0.30 searchability%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-RANK-45' data-look='classic' transform='translate(1499.83203125%2c 932.2132339477539)'%3e%3crect class='basic label-container' style='' x='-117.671875' y='-27' width='235.34375' height='54'/%3e%3cg class='label' style='' transform='translate(-87.671875%2c -12)'%3e%3crect/%3e%3cforeignObject width='175.34375' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eRanking across all JDs%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-REP-47' data-look='classic' transform='translate(138%2c 1465.4264678955078)'%3e%3crect class='basic label-container' style='' x='-130' y='-63' width='260' height='126'/%3e%3cg class='label' style='' transform='translate(-100%2c -48)'%3e%3crect/%3e%3cforeignObject width='200' height='96'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3ePer-JD report%3cbr /%3egauge%2c skill table%2c searchability%2c register%2c discovered%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-EXP-59' data-look='classic' transform='translate(138%2c 1629.4264678955078)'%3e%3crect class='basic label-container' style='' x='-130' y='-51' width='260' height='102'/%3e%3cg class='label' style='' transform='translate(-100%2c -36)'%3e%3crect/%3e%3cforeignObject width='200' height='72'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eExport packet%3cbr /%3eMarkdown %2b JSON%2c self-contained%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-ADD-61' data-look='classic' transform='translate(1775.00390625%2c 716)'%3e%3crect class='basic label-container' style='' x='-125.6953125' y='-27' width='251.390625' height='54'/%3e%3cg class='label' style='' transform='translate(-95.6953125%2c -12)'%3e%3crect/%3e%3cforeignObject width='191.390625' height='24'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eWrite term to taxonomy%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='node default' id='mermaid-0-flowchart-AI-65' data-look='classic' transform='translate(1033.5%2c 1793.4264678955078)'%3e%3crect class='basic label-container' style='' x='-126.6796875' y='-39' width='253.359375' height='78'/%3e%3cg class='label' style='' transform='translate(-96.6796875%2c -24)'%3e%3crect/%3e%3cforeignObject width='193.359375' height='48'%3e%3cdiv xmlns='http://www.w3.org/1999/xhtml' style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b'%3e%3cspan class='nodeLabel'%3e%3cp%3eExternal AI tool%3cbr /%3etailors resume truthfully%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/g%3e%3cdefs%3e%3cfilter id='mermaid-0-drop-shadow' height='130%25' width='130%25'%3e%3cfeDropShadow dx='4' dy='4' stdDeviation='0' flood-opacity='0.06' flood-color='black'/%3e%3c/filter%3e%3c/defs%3e%3cdefs%3e%3cfilter id='mermaid-0-drop-shadow-small' height='150%25' width='150%25'%3e%3cfeDropShadow dx='2' dy='2' stdDeviation='0' flood-opacity='0.06' flood-color='black'/%3e%3c/filter%3e%3c/defs%3e%3c/svg%3e)
How the Matching Works
Early on, I extracted keywords directly from each job description and scored against them. The results were noisy: vague phrases, company names, boilerplate, and near synonyms landing on opposite sides of the match line. The fix was to stop guessing at keywords and match against a curated dictionary of known skills instead.
The heart of the tool is a skills taxonomy stored as an editable YAML file. Each entry holds a canonical skill name, a list of surface forms and aliases, a hard-or-soft type, an optional register tag, and case-sensitivity rules. Matching is word-boundary occurrence counting against those forms, which gives clean, explainable results instead of fuzzy approximations.
  - name: "Release Train Engineer"
    type: hard
    forms: ["Release Train Engineer", "RTE"]
For every required skill in a job description, the tool reports one of three states:
- Matched: the resume and the JD share the same form
- Variation: both have the skill, but worded differently (resume says “Agilist,” JD says “Agile”)
- Missing: the JD requires it and the resume has nothing
Short all-caps acronyms like FAR, SOW, RMF, and ATO are matched case-sensitively so they never trigger on lowercase English words, and a few deliberately case-locked terms like SAFe avoid false hits on common words.
Features
Composite Match Rate
A single, explainable score per job description, broken into hard skills, soft skills, and searchability, shown as a gauge with a category breakdown. The weighting is transparent: 55 percent hard skills, 15 percent soft, 30 percent searchability. A semantic similarity score runs alongside as a supplemental context signal rather than the headline number.
Searchability and Format Checks
Deterministic checks for the literal reasons an ATS rejects a resume: exact job title match, contact information, section headings, education level against the posting, date formatting, and quantified results. No fuzzy matching, just the format hygiene that gets resumes auto-filtered.
Multi-JD Comparison
Load several postings at once and rank them by composite match, with a per-JD detailed breakdown in its own tab. This shows me, at a glance, which openings I am naturally strongest for.
Discovered Terms with Persistent Click-to-Add
After each scan, the tool surfaces skill-like phrases a job description uses that my taxonomy does not yet track. One click promotes a term into the vocabulary, written straight back to the YAML file on disk. Because the loader is cached on the file’s modification time, the change goes live on the next scan with no restart and no manual refresh, and it survives reboots. The vocabulary grows from my real job search instead of being maintained by hand.
Register-Conflict Detection
Because I apply to both government and commercial roles, each posting carries a target register: Neutral, Commercial, or Government. When I aim a resume at a commercial role, the tool flags government and defense jargon sitting in it, the kind a commercial recruiter reads as untranslated govspeak, and tells me to translate or cut it. When I aim at a federal role, it nudges me if the resume reads too soft and corporate. Each posting is judged on its own register, so I can run commercial and federal applications in the same batch and have each one evaluated correctly.
Naming-Churn Handling
The Department of Defense is being renamed the Department of War. The term is in active use while the legal change works through Congress, so real postings use both names. The tool treats “Department of War,” “Department of Defense,” “DoW,” and “DoD” as one skill, so a posting scores the same either way and my resume matches whichever form I wrote.
AI Handoff Packets
The strongest generative AI I have access to is commercial, and the real bottleneck for good suggestions is the context you hand the model. So instead of building weaker local generation in, the tool assembles a self-contained packet per job, my resume, the full posting, and the computed gaps, in both a readable Markdown format and an upload-and-go JSON. I hand one file to a frontier model with a built-in instruction to rewrite my experience truthfully toward the gaps and never invent anything, then I review every suggestion before it touches my actual resume. The tool measures, the strong model drafts, and I stay the human in the loop.
Design Decisions
Curated taxonomy over open-vocabulary extraction. Trying to extract keywords from arbitrary text produced too much noise and too many false gaps from near synonyms. A focused, hand-tunable vocabulary tuned to my role cluster gives clean, trustworthy results. The tradeoff is that anything phrased a way the taxonomy does not track reads as a gap, which the discovered-terms loop closes over time.
Local-first. Everything runs on my own machine. No external services, no accounts, no per-scan cost, which matters for a tool I run dozens of times a day.
Measurement local, generation external. Local language models I can run are not as deep as I need for resume rewriting, so I deliberately kept the generation work routed to a frontier model and used the tool to produce a perfect, self-contained context packet for it.
Data, not code, holds the knowledge. The skills taxonomy and the register tags live in a plain YAML file. I can hand-edit it, version it in git, or grow it by clicking in the app, all without touching the matching logic.
Limitations
- The match rate is a proxy for how an ATS behaves, not a readout of any specific employer’s system.
- The taxonomy is tuned to my target roles. Outside that lane it is far less useful by design.
- It is decision support, not a guarantee. Clearing the bar gets me visible, not hired, and referrals still do the heaviest lifting.
- The AI handoff always requires my review, since a model can produce a plausible but inaccurate bullet.
Status
The tool is built, tested, and in active use across my job search. It runs locally and does the one thing I needed: tell me, before I submit, whether a resume is going to clear the gate for a specific posting. Possible future work includes containerizing it and exposing it securely so I can reach it from anywhere, but that is a convenience rather than a requirement.